Big Data Analytics Framework for Intelligent Decision Support Systems
DOI:
https://doi.org/10.65521/ijacte.v11i1.4113Keywords:
Abstract
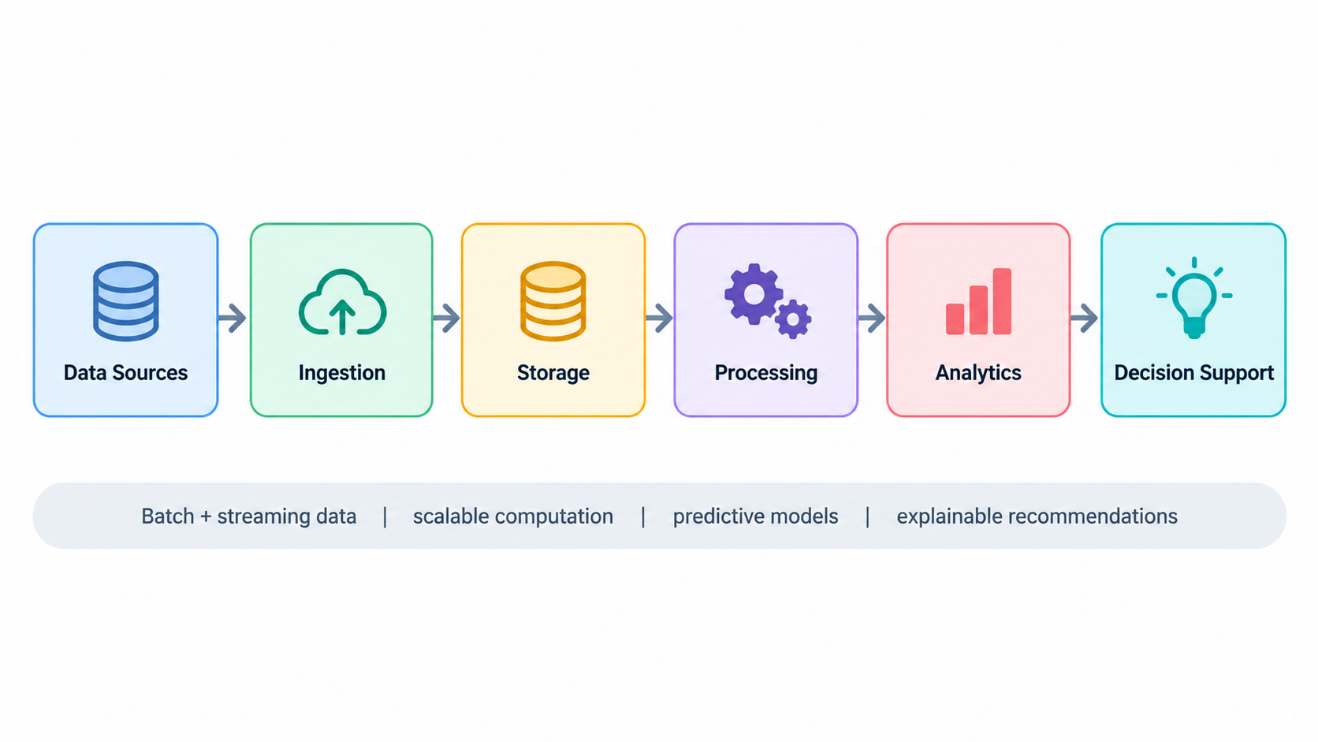
The rapid growth of heterogeneous, high-velocity and high-volume data has created a need for decision support systems that can transform distributed data into timely and explainable recommendations. This paper proposes a scalable Big Data Analytics Framework for Intelligent Decision Support Systems (IDSS) that integrates data ingestion, distributed storage, parallel processing, predictive analytics, knowledge-based reasoning and interactive visualization. The methodology adopts a design-science and prototype-evaluation approach. Structured transactional records, semi-structured logs and streaming events are passed through data-quality controls, stored in a distributed data lake, transformed using batch and stream processing, and analyzed through descriptive, predictive and prescriptive models. A decision layer converts model outputs into ranked alternatives using confidence thresholds, business rules and user-defined criteria. The framework is evaluated using a controlled synthetic workload that represents increasing data volume and decision complexity. Illustrative results indicate that distributed processing substantially reduces analytical latency while machine-learning-assisted recommendations improve classification accuracy and decision consistency. The proposed architecture emphasizes scalability, modularity, governance, auditability and human oversight, making it suitable as a general methodological blueprint for intelligent decision support in business, healthcare, public administration and other data-intensive settings.